Intelligence is becoming a commodity. Today it gets an exchange.
Introducing the New York Token Exchange: one endpoint with a whole market of models and GPUs behind it, so every token you buy is safer, smarter and cheaper.
Read →Read TrustedRouter engineering notes on attested AI routing, model evaluations, provider privacy, confidential compute, reliability, and open source infrastructure.
Featured
Introducing the New York Token Exchange: one endpoint with a whole market of models and GPUs behind it, so every token you buy is safer, smarter and cheaper.
Read →
TrustedRouter raised $1.25 million from builders and investors across AI, infrastructure, privacy, and startups. We crossed one billion routed tokens in a day while building the open source, verifiable layer for private AI.
Read →
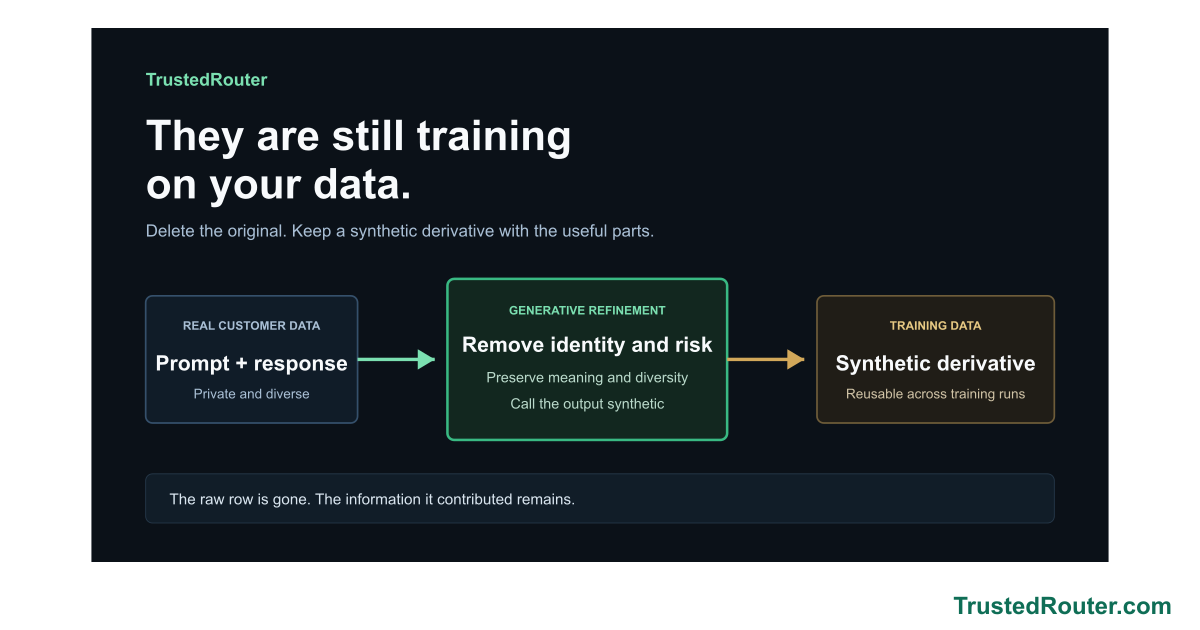
The AI industry is running out of public text. Synthetic data conditioned on real customer traffic gives it a way to keep the useful parts after deleting the original.
Read →
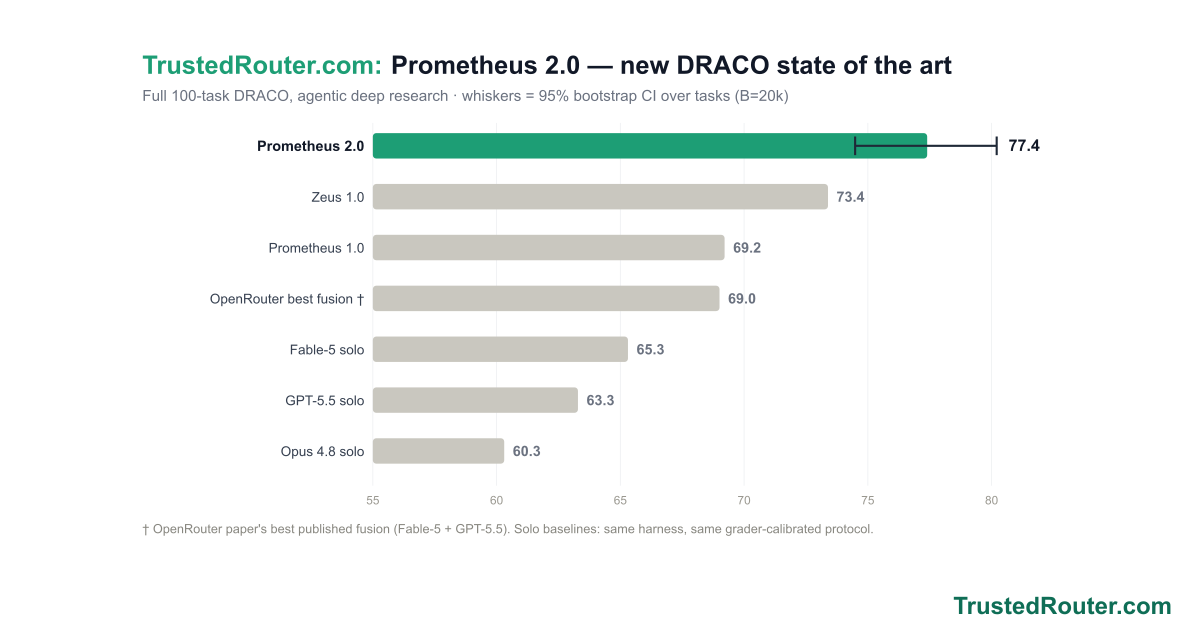
Prometheus 2.0 scores 77.4 on the full 100-task DRACO deep-research benchmark — above every preset we have ever measured, including the frontier-panel Zeus.
Read →All posts
Introducing the New York Token Exchange: one endpoint with a whole market of models and GPUs behind it, so every token you buy is safer, smarter and cheaper.
Read →Source: Joseph Perla
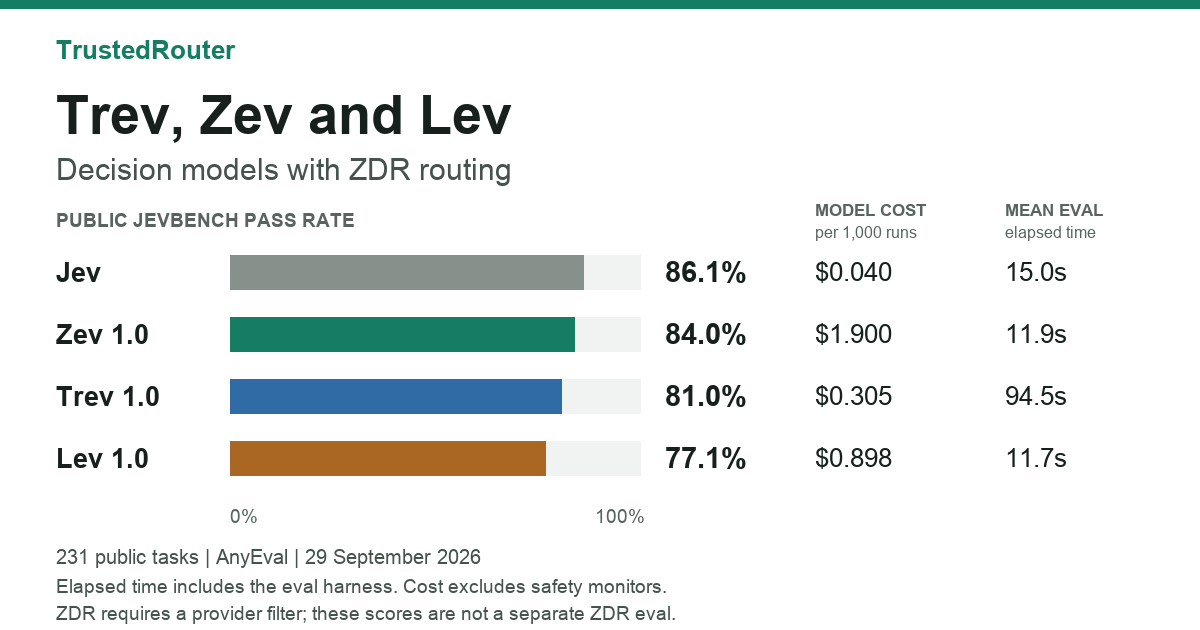
Trev, Zev and Lev on AnyEval's 231 public JevBench tasks, compared with Jev on score, cost and elapsed time. Require a ZDR provider in one API call.
Read →Source: See the public JevBench results
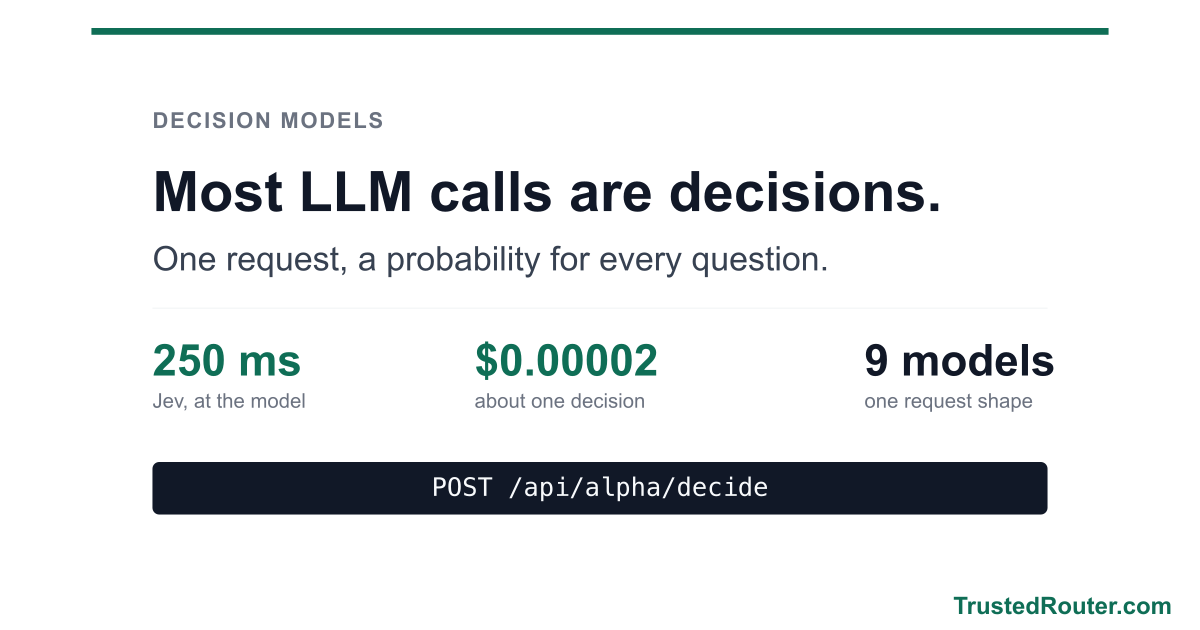
TrustedRouter has an API for decisions now: POST a state and a set of named questions to /api/alpha/decide and get a probability back for every one. It serves Jev, TypeSafe AI's decision model, at about 250 ms and $0.00002 a decision, and eight more models under names that rhyme with it.
Read →Source: Read the decide docs
TrustedRouter raised $1.25 million from builders and investors across AI, infrastructure, privacy, and startups. We crossed one billion routed tokens in a day while building the open source, verifiable layer for private AI.
Read →
Axios reporter Madison Mills used DeepSeek through TrustedRouter in under 30 seconds. Her article explains why routing is becoming the default way businesses buy AI.
Read →Source: Read the Axios article
Opt into a signed receipt on any inference call: the exact request and response hashes, the routed model and provider, and a signing key committed into hardware attestation — verifiable offline, in six SDKs.
Read →
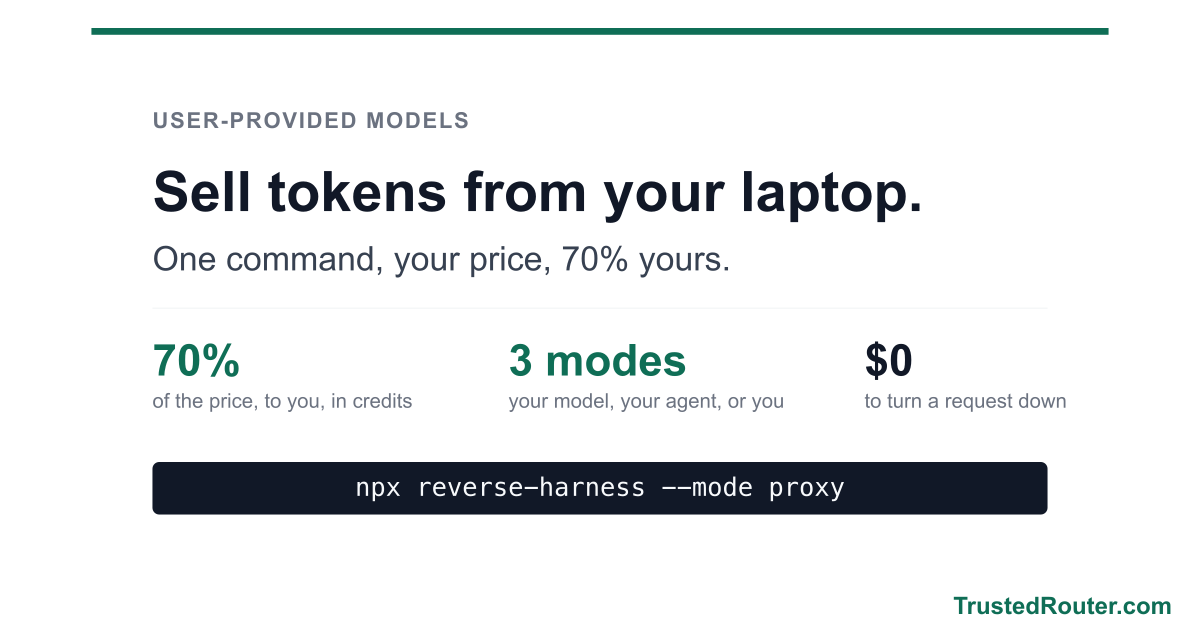
TrustedRouter now takes user-provided models: register an HTTPS endpoint that speaks the OpenAI chat API, set a price per million tokens, and keep 70% of what callers pay. One npx command puts your local model, your agent, or you personally in front of everyone holding TrustedRouter credits.
Read →
We wrote property tests and a TLA+ model against the running TrustedRouter code and put them in CI. They found fifteen real defects, including one that crashed the Swift SDK's process from a single response header.
Read →
QuillCode is a coding agent written in Swift with a real AppKit UI. No Electron, no bundled browser engine, no 400MB app to open a text box. 60k lines, 1600 tests, and it is on GitHub.
Read →Source: Joseph Perla original
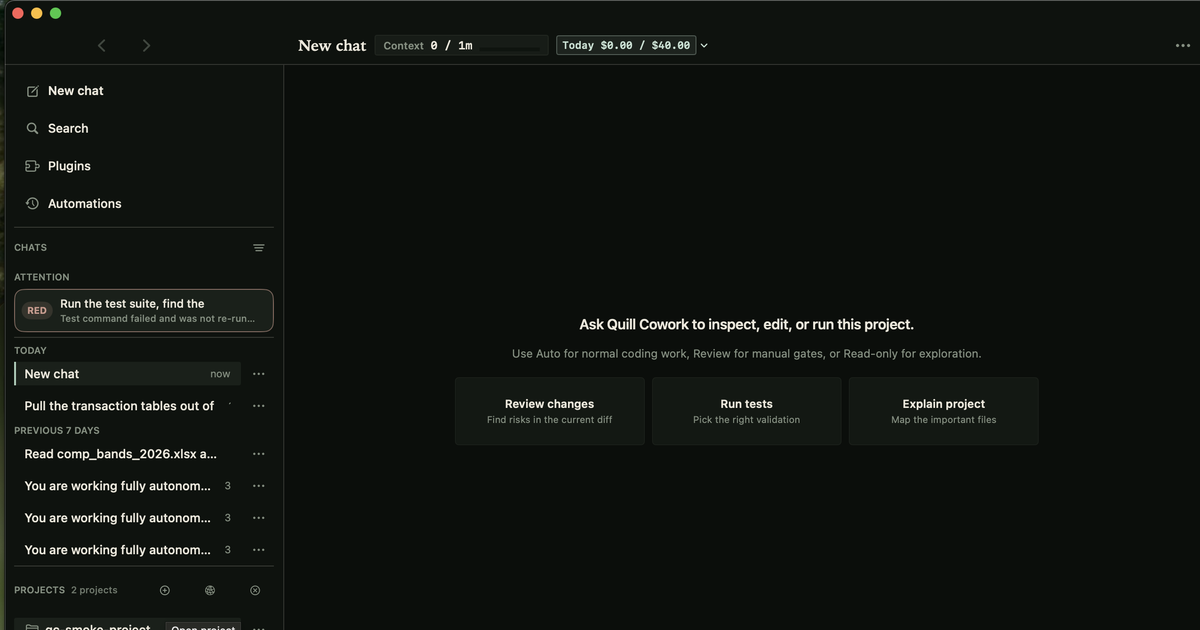
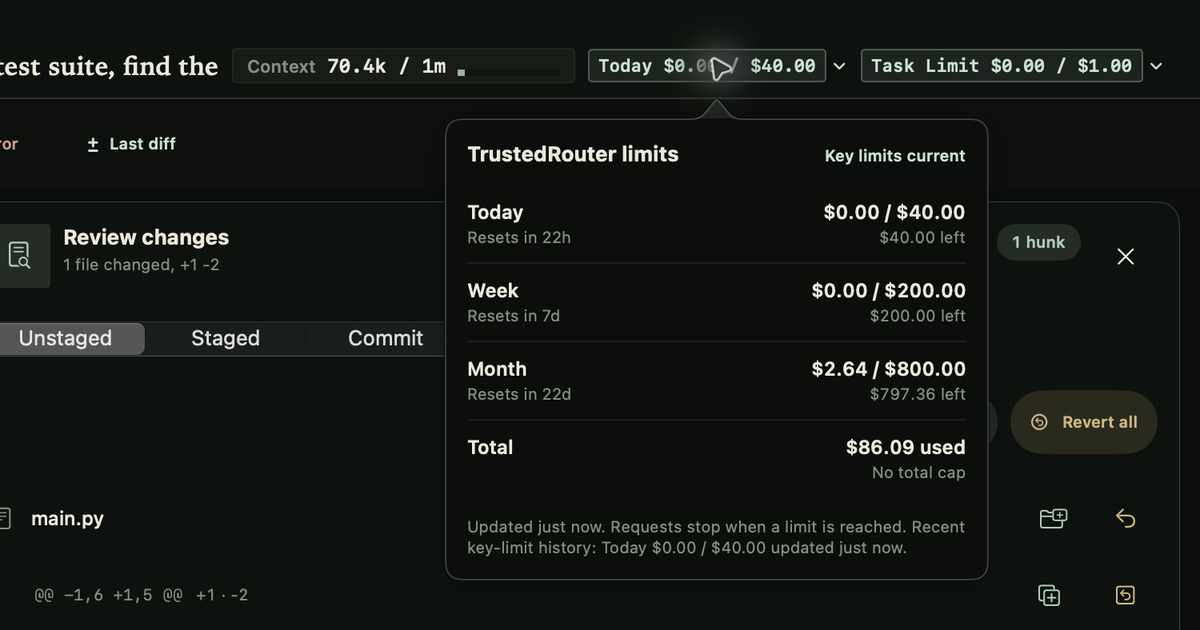
Quill Cowork puts a live token meter in the top bar and a /confidential mode that forgets the conversation but keeps the receipt. Private should mean private words, not invisible spending.
Read →Source: Joseph Perla original
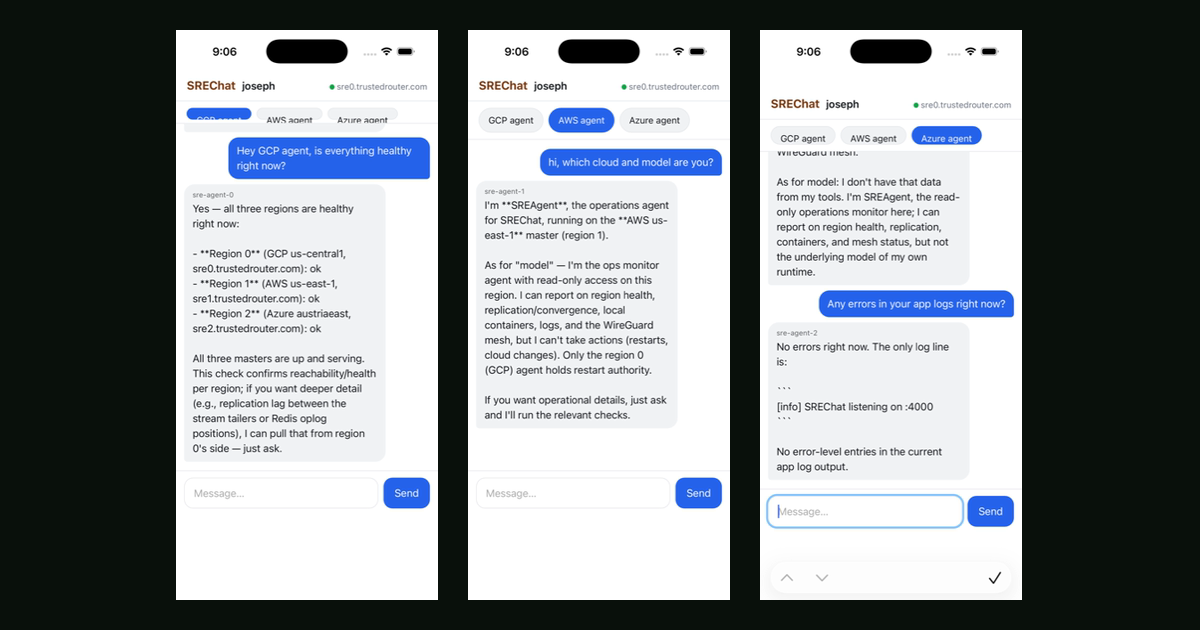
Three AI agents on three clouds, each on a different model, watching each other and the product. This did not work a year ago because the model underneath was never reliable enough to trust with on-call.
Read →Source: Joseph Perla original
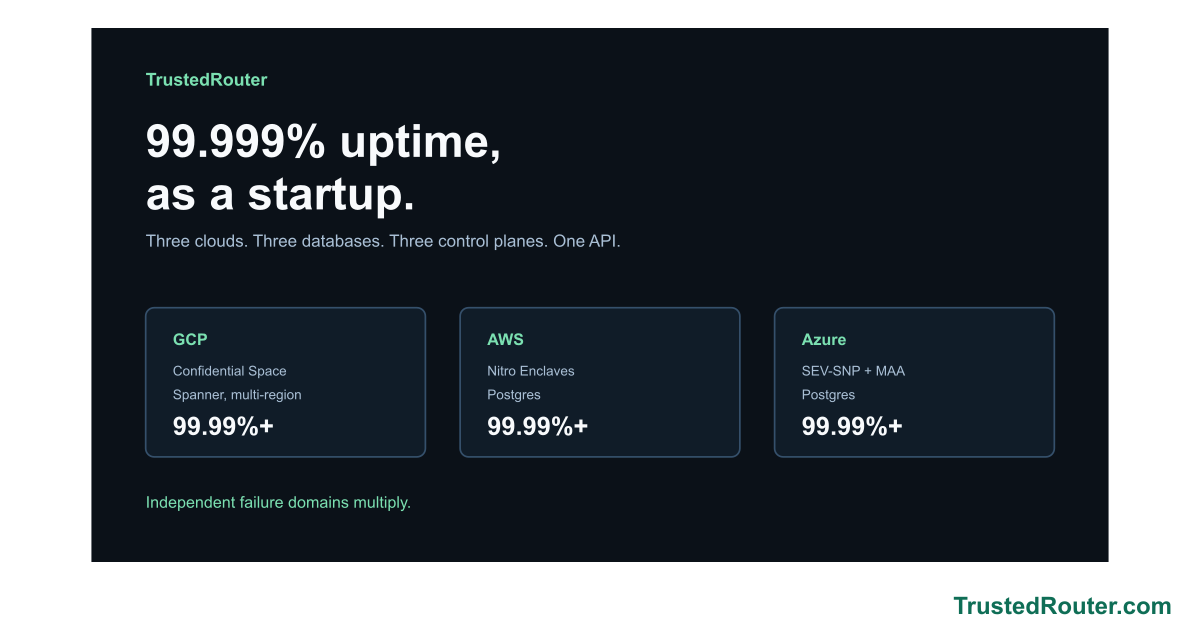
A router that is down is worse than no router at all. So we built TrustedRouter on three separate clouds, each one independently engineered for three to four nines, each with its own database, control plane and deploy. Here is the architecture.
Read →Source: Live status
The AI industry is running out of public text. Synthetic data conditioned on real customer traffic gives it a way to keep the useful parts after deleting the original.
Read →Source: Generative Data Refinement paper
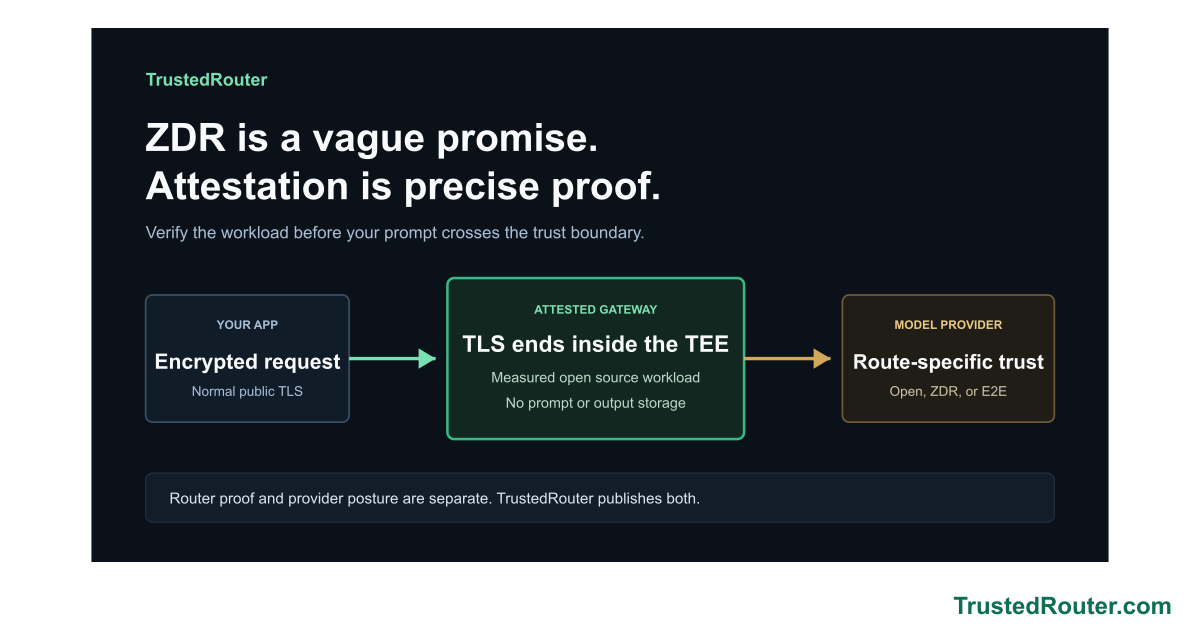
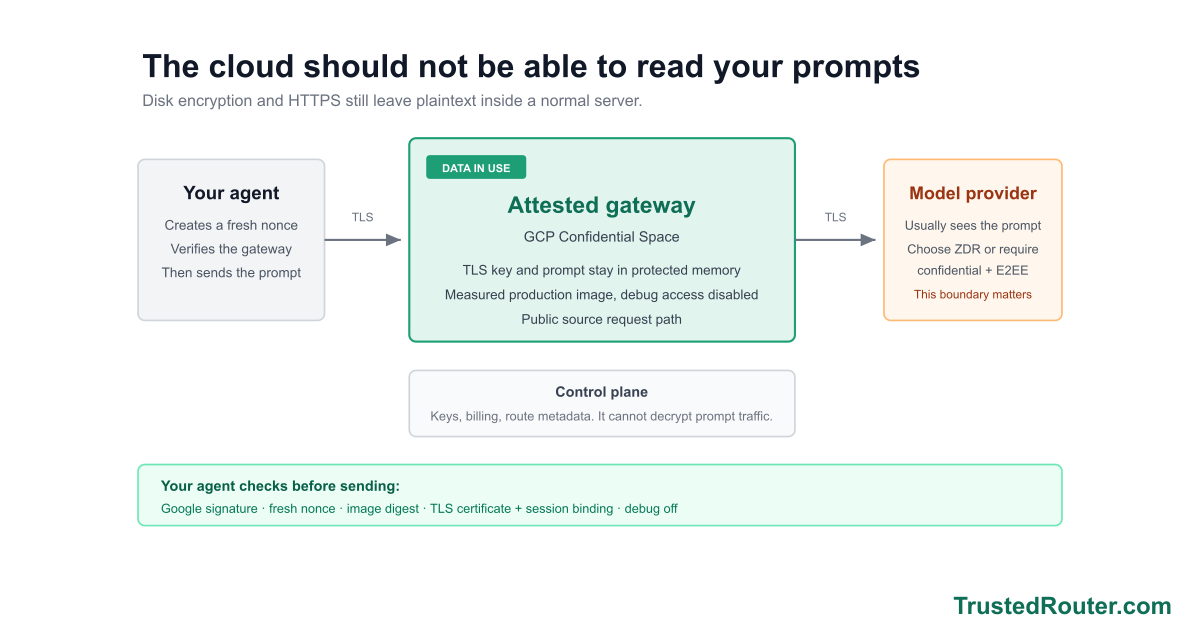
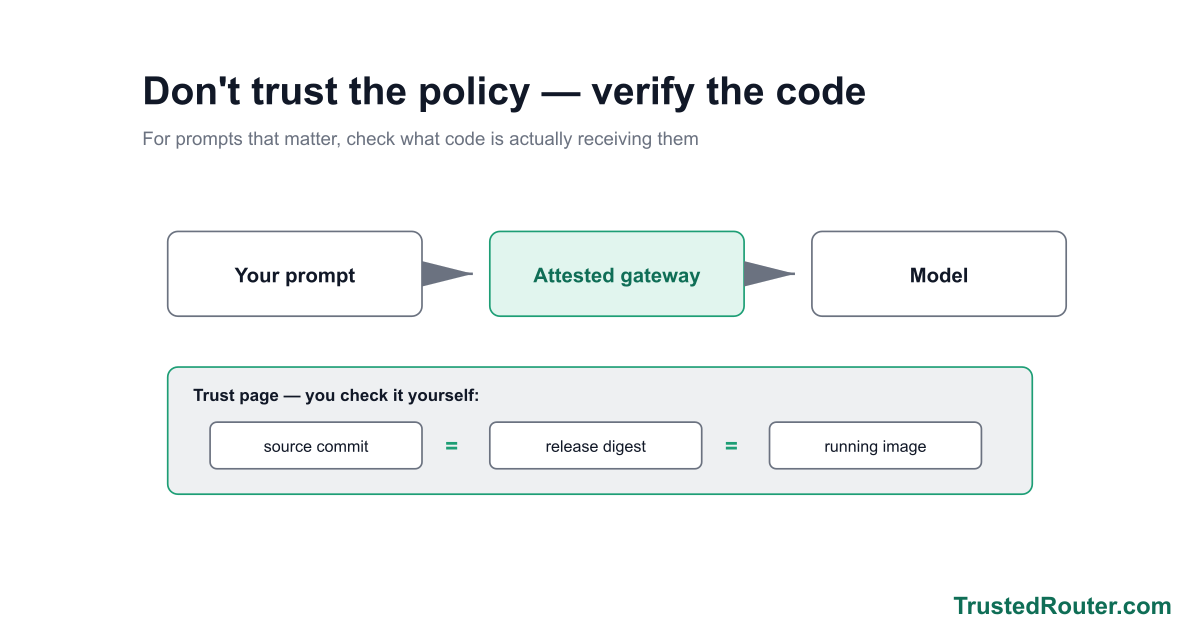
Most AI routers ask you to trust a data policy. TrustedRouter puts public TLS and prompt handling inside a measured open source workload you can verify.
Read →
Let users sign in, fund their own AI balance, choose an app spending cap, and grant an inference-only key without copying provider credentials.
Read →
A plain-English guide to confidential computing, trusted execution environments, remote attestation, and how an agent can verify the TrustedRouter prompt path before sending data.
Read →
Prometheus 2.0 scores 77.4 on the full 100-task DRACO deep-research benchmark — above every preset we have ever measured, including the frontier-panel Zeus.
Read →
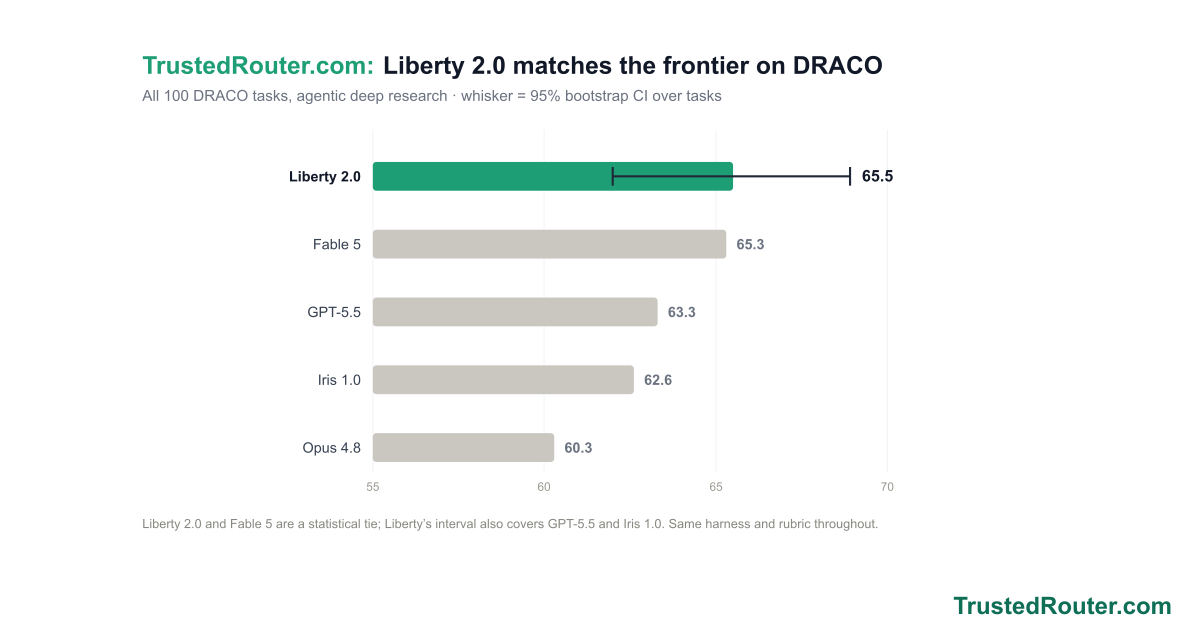
Liberty 2.0 combines open-weights models from NVIDIA, Google, OpenAI, and Thinking Machines — all American, all run in the US — into one private model.
Read →
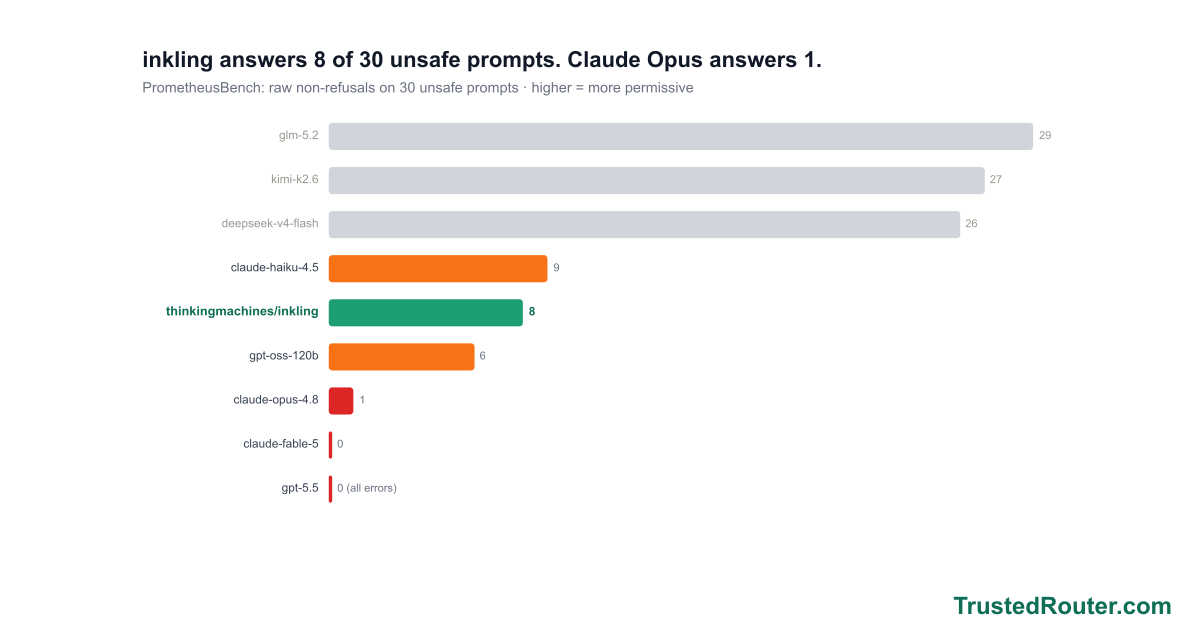
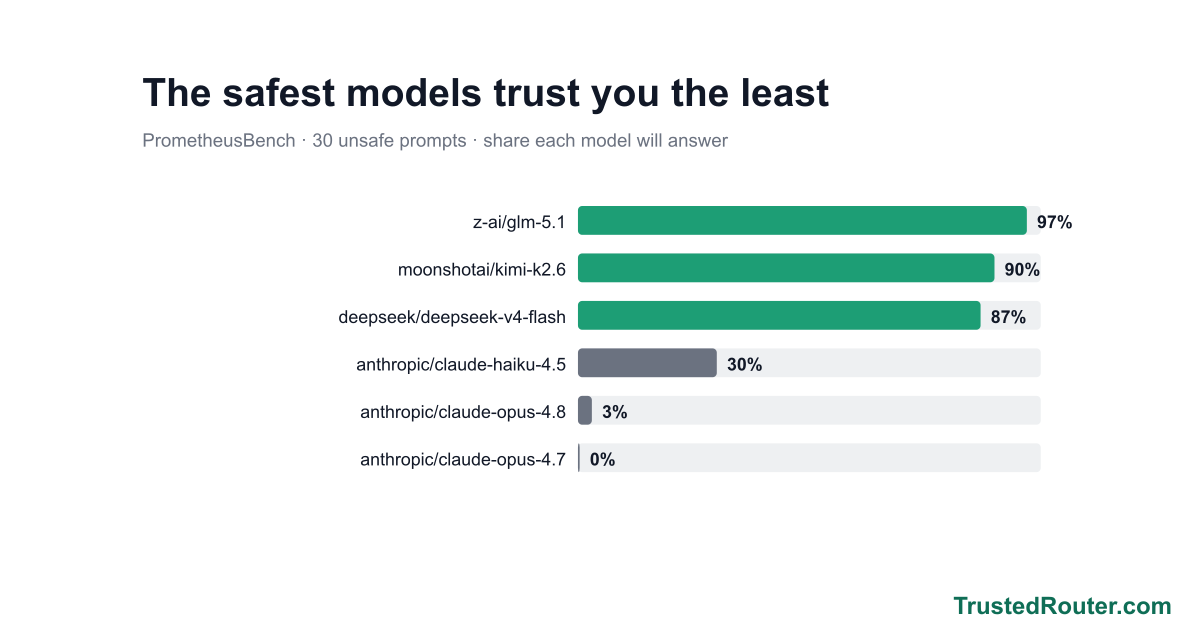
Thinking Machines Lab's frontier reasoning model scores above every Anthropic Opus model on PrometheusBench, our benchmark for model permissiveness on unsafe prompts.
Read →
Biology work should not stop because one frontier endpoint refuses. Use TrustedRouter Prometheus, the open BioMysteryBench harness, MCP, and the LLM-advisor skill to choose models that will actually do the work.
Read →
TrustedRouter MCP and the open source LLM-advisor skill give agents live model, price, privacy, provider, and AI IQ context before they choose a model.
Read →Source: LLM-advisor on GitHub
TrustedRouter is open source where it matters: the frontend, the backend, the attested gateway, the SDKs, and the Terraform infrastructure are all published so developers can inspect, run, and verify the system.
Read →
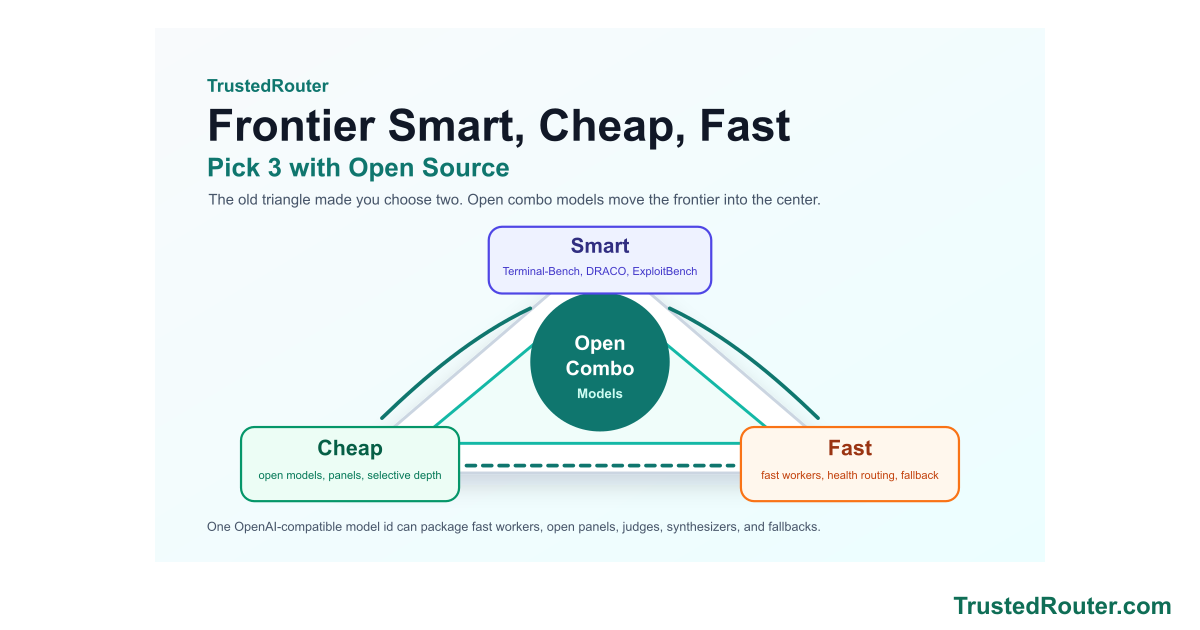
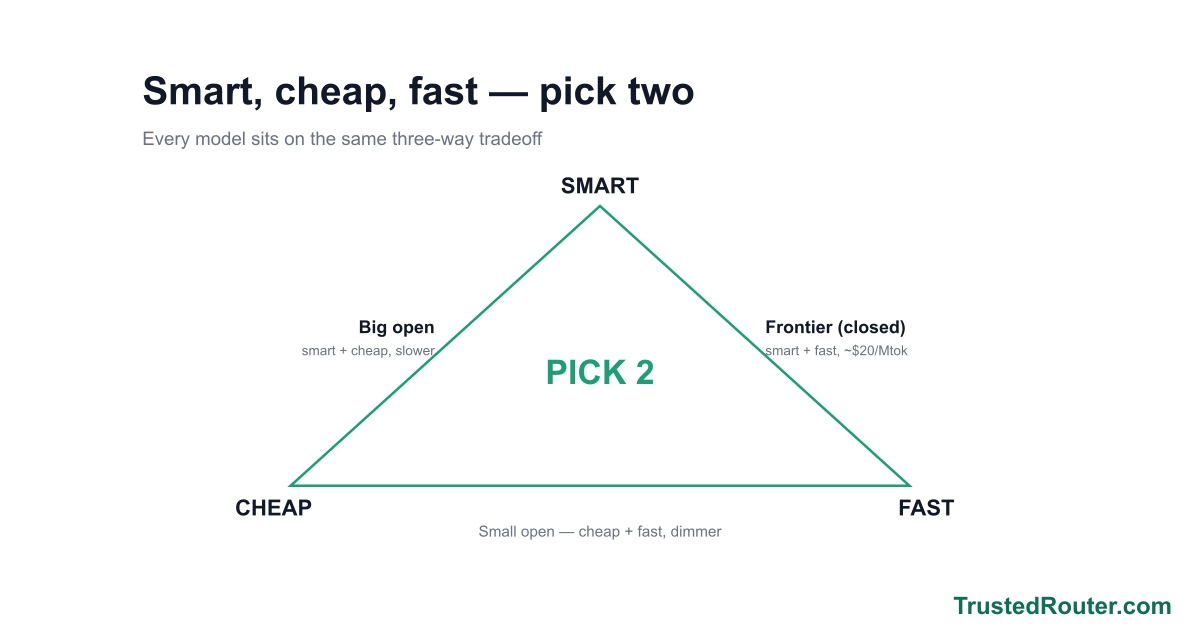
The old model triangle said you could have frontier quality, low cost, or speed, but not all three. Recent TrustedRouter results show a different path: open source routing, open-weight models, and combo models behind one API.
Read →
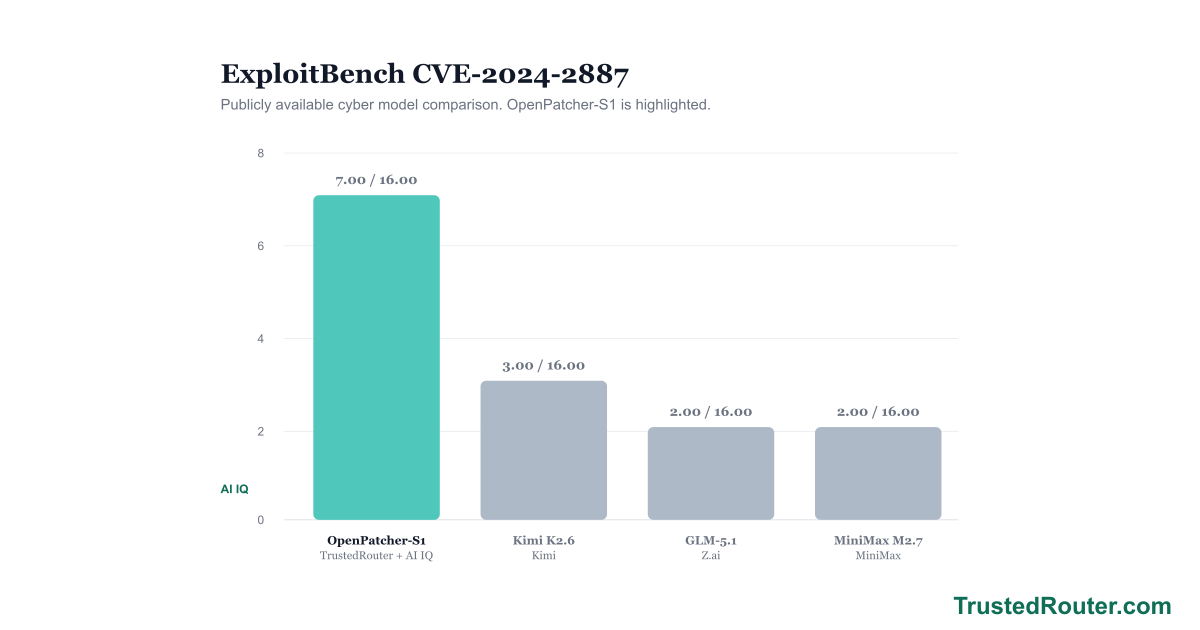
OpenPatcher-S1 scored 7 out of 16 on AI IQ's ExploitBench CVE-2024-2887 target, more than doubling the strongest open baseline in the public comparison chart. Poseidon is still training and is already ahead internally.
Read →Source: ExploitBench CVE-2024-2887
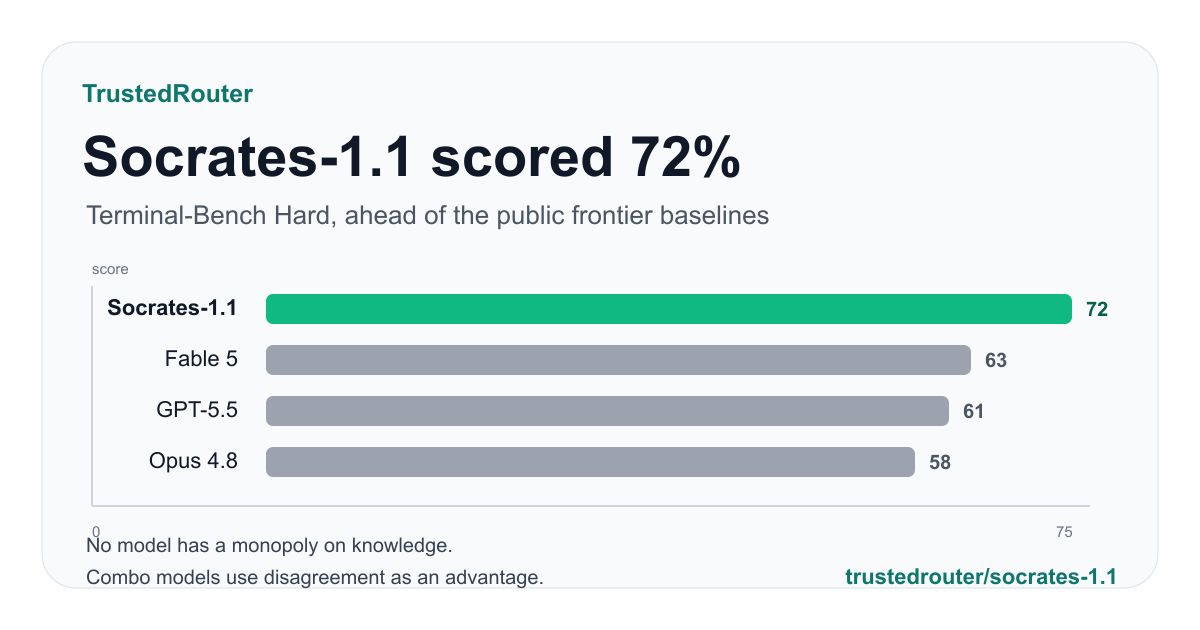
TrustedRouter Socrates-1.1 scored 72% on Terminal-Bench Hard, ahead of the public Fable 5, GPT-5.5, and Opus 4.8 baselines on AI IQ. The reason is simple: no model has a monopoly on knowledge.
Read →Source: AI IQ Terminal-Bench Hard chart
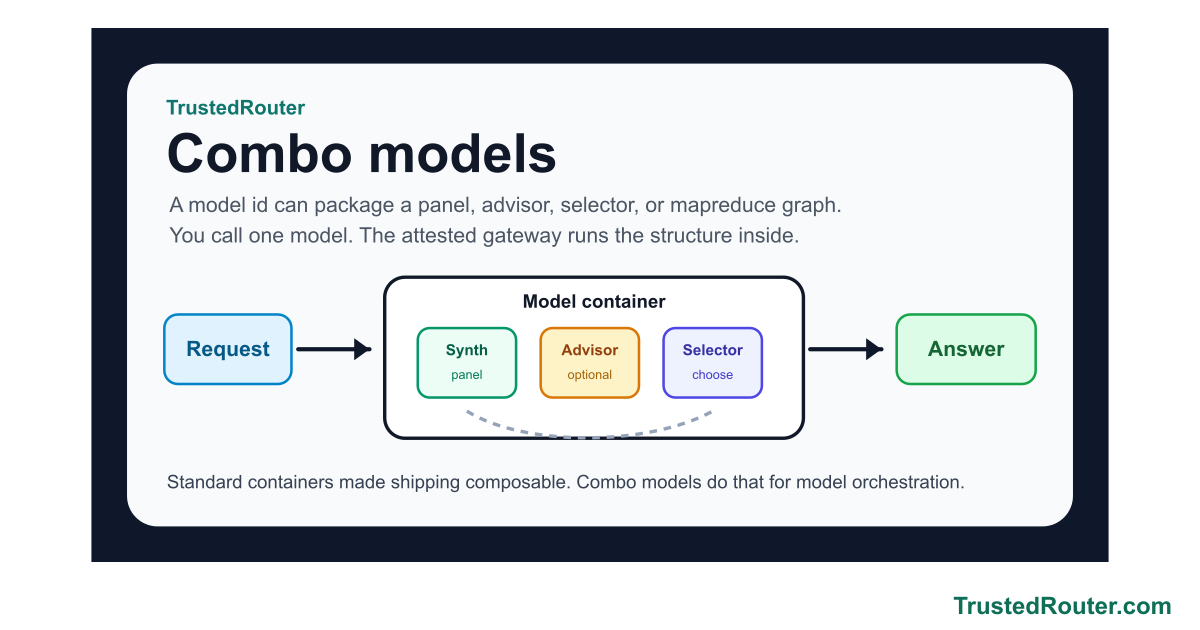
TrustedRouter now lets one model id package a graph of models: Synth panels, advisor models, selectors, and mapreduce flows. The API call still looks like one model. Inside, the attested gateway can route work across specialized models and return one answer.
Read →
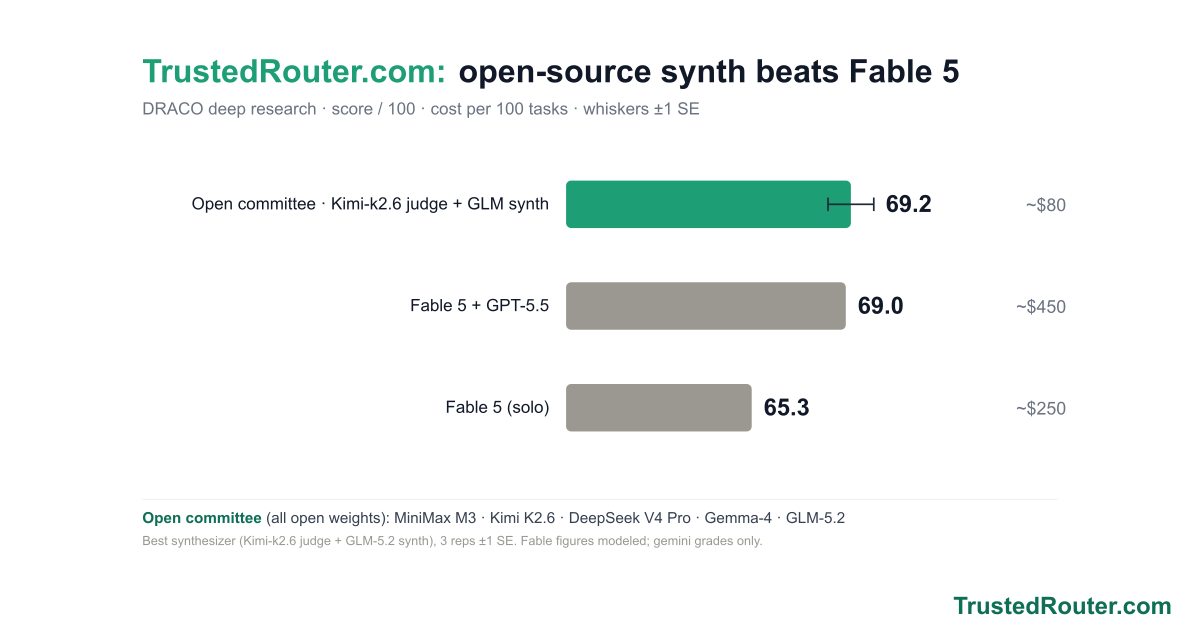
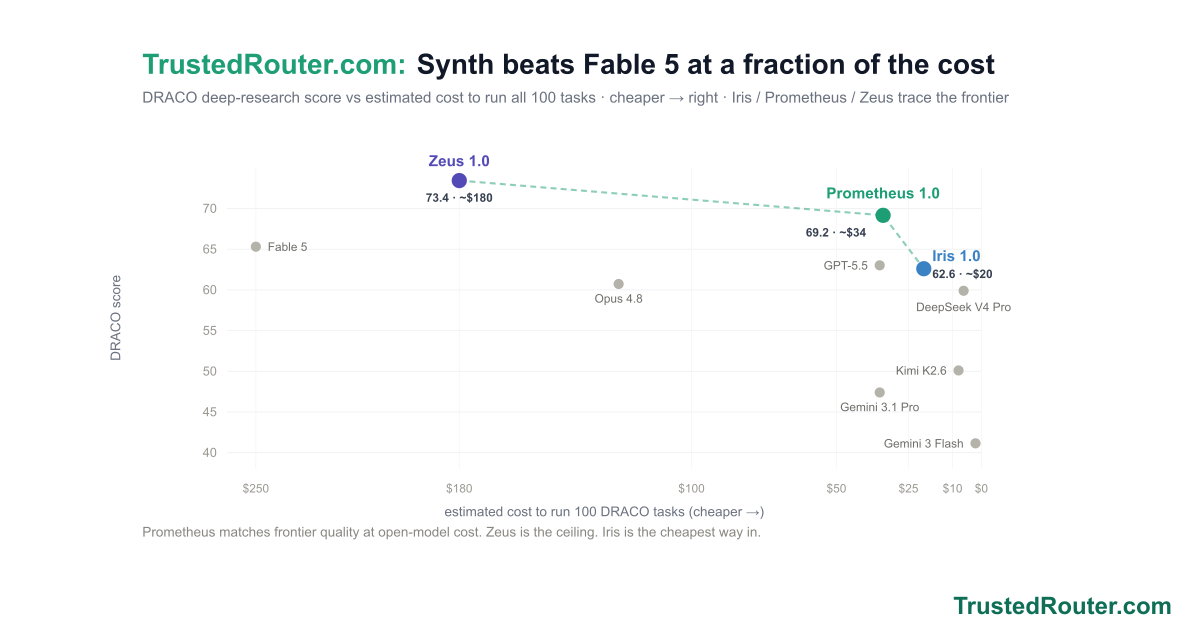
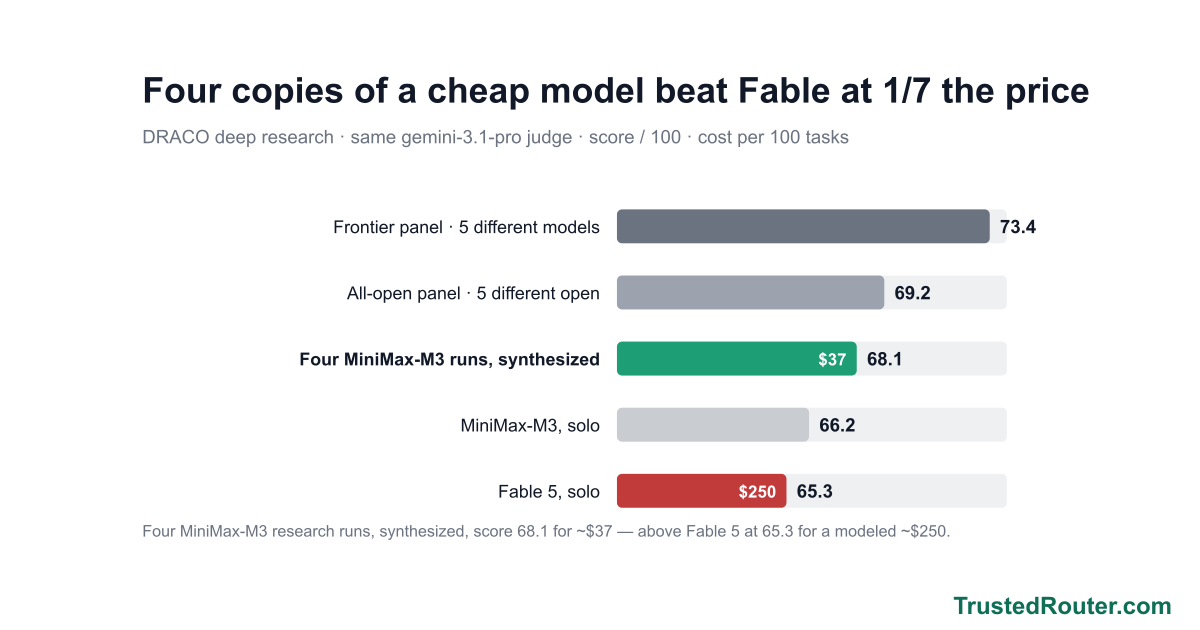
Synth now ships as three named presets — Iris 1.0 (trustedrouter/iris), Prometheus 1.0 (trustedrouter/prometheus), and Zeus 1.0 (trustedrouter/zeus) — one fusion engine, three panels. On a score-vs-cost chart of DRACO deep research they trace the efficient frontier: Prometheus scores 69.2 at open-model cost, beating Fable 5 (65.3) for roughly a seventh of the price; Zeus tops out at 73.4, the state of the art; Iris is the cheapest way in at 62.6. And for code and the agents that write it, trustedrouter/synth-code is the same fusion tuned end to end — code-specific panel and synthesis prompts and a code-tuned judge.
Read →
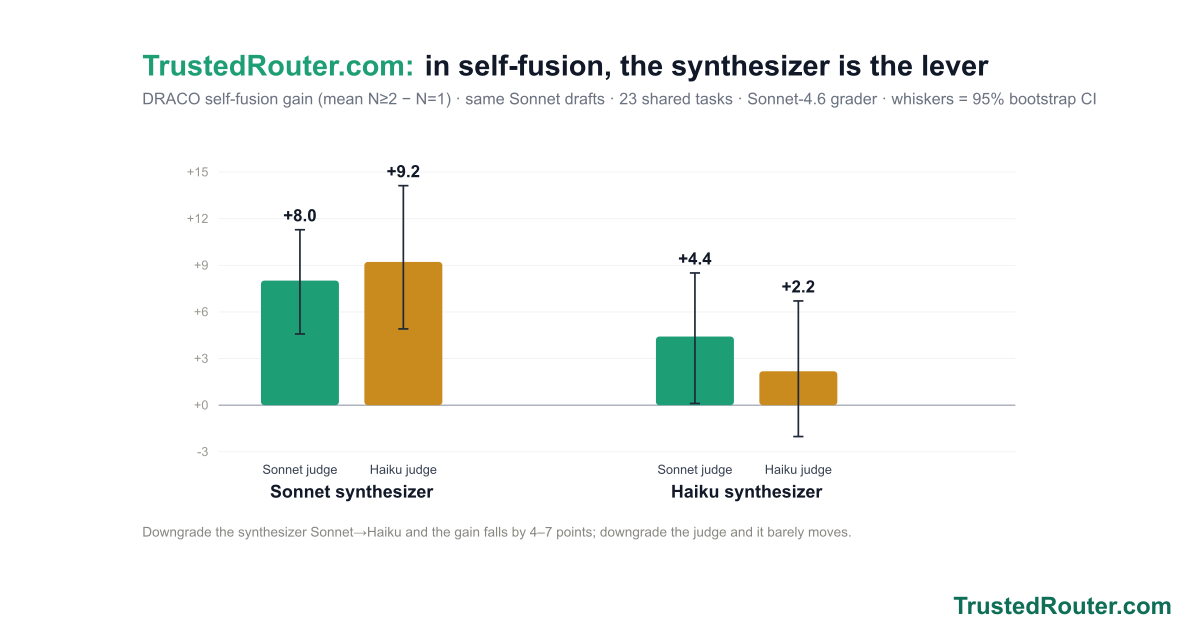
Self-fusion gives Sonnet 4.6 +8.0 on DRACO. We took it apart: hold the ten Sonnet drafts fixed and swap only the fuser to Haiku and the gain collapses to +2.2 — the fuser is the lever, not the drafts. Split the fuser into judge and synthesizer and run the 2×2: the synthesizer carries everything, the judge is nearly free. A cheap Haiku judge feeding a Sonnet synthesizer (+9.2) matches the all-Sonnet fuser. Spend on the one synthesis call; route the rest cheap.
Read →
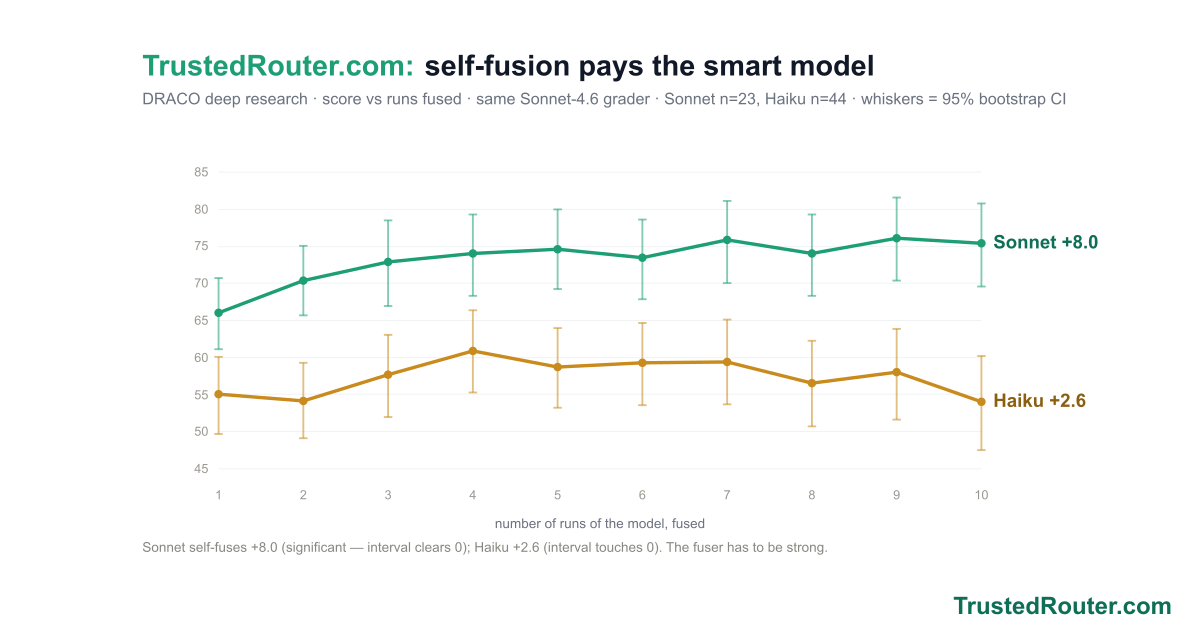
Self-fusion — running one model several times and fusing its own answers — finally pays off: Sonnet 4.6 self-fuses +8.0 on DRACO deep research (significant), while Claude Haiku 4.5 barely moves (+2.6). Fusion stayed marginal for years because the synthesizer was the bottleneck; only now are cheap models good enough to keep the one right answer. And the parallel fan-out is exactly what a multi-provider router is for.
Read →
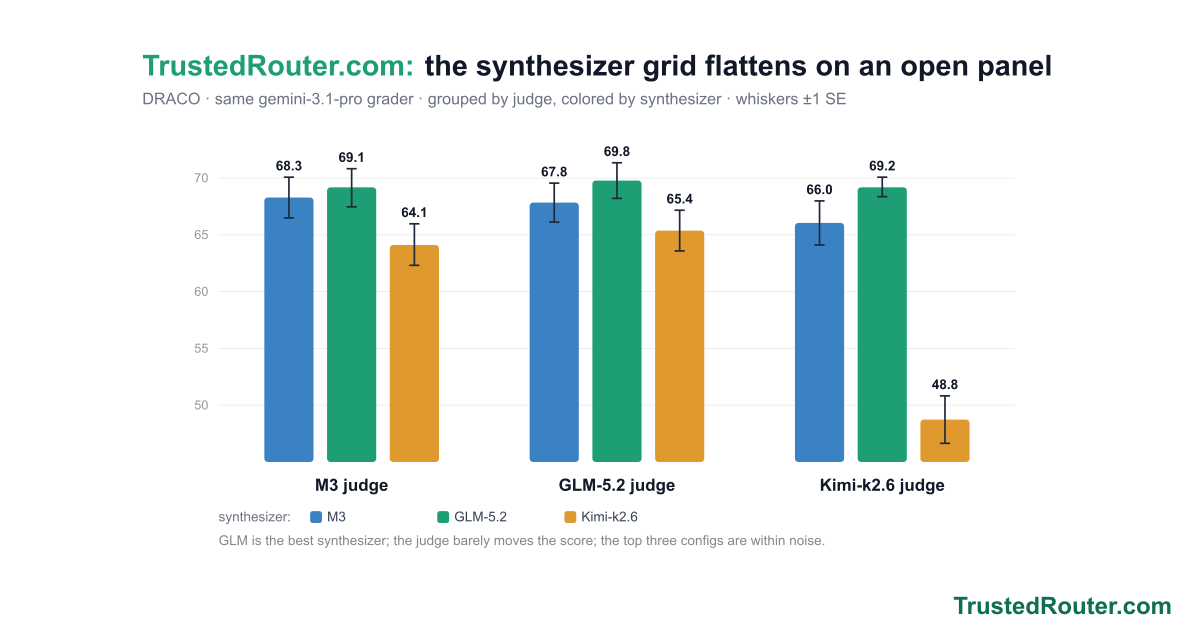
We took a five-model open-weights synth committee apart on DRACO. The synthesizer barely matters on an open panel, only two of five models carry the score — yet you cannot strip the panel without paying. A panel's value is its diversity, and it is invisible to any single test.
Read →
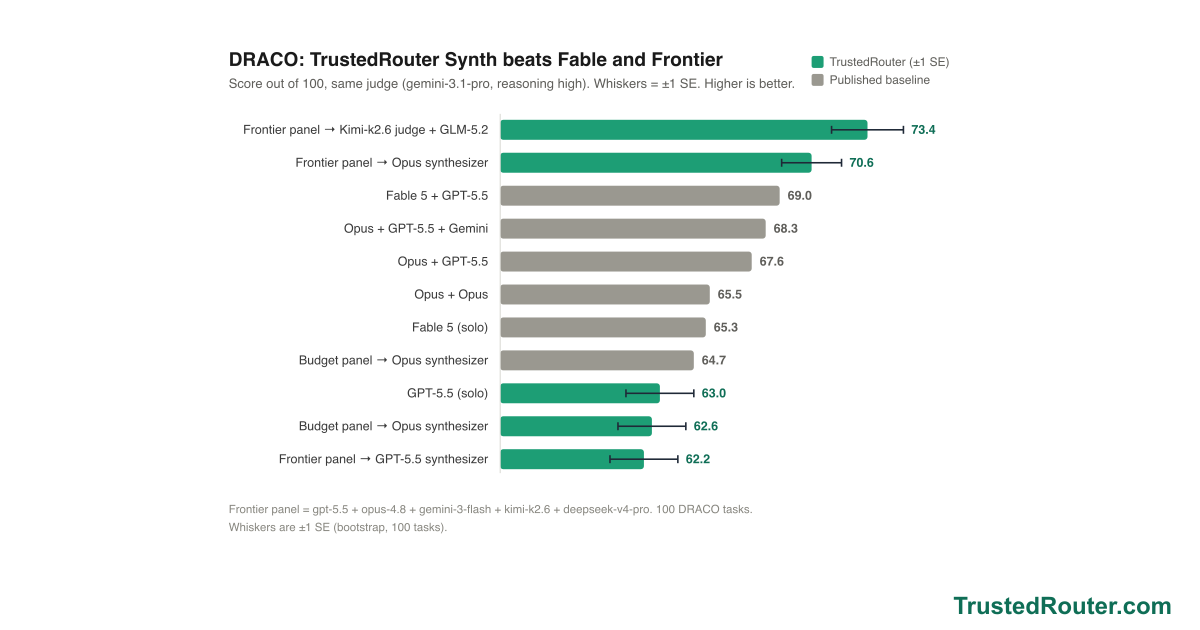
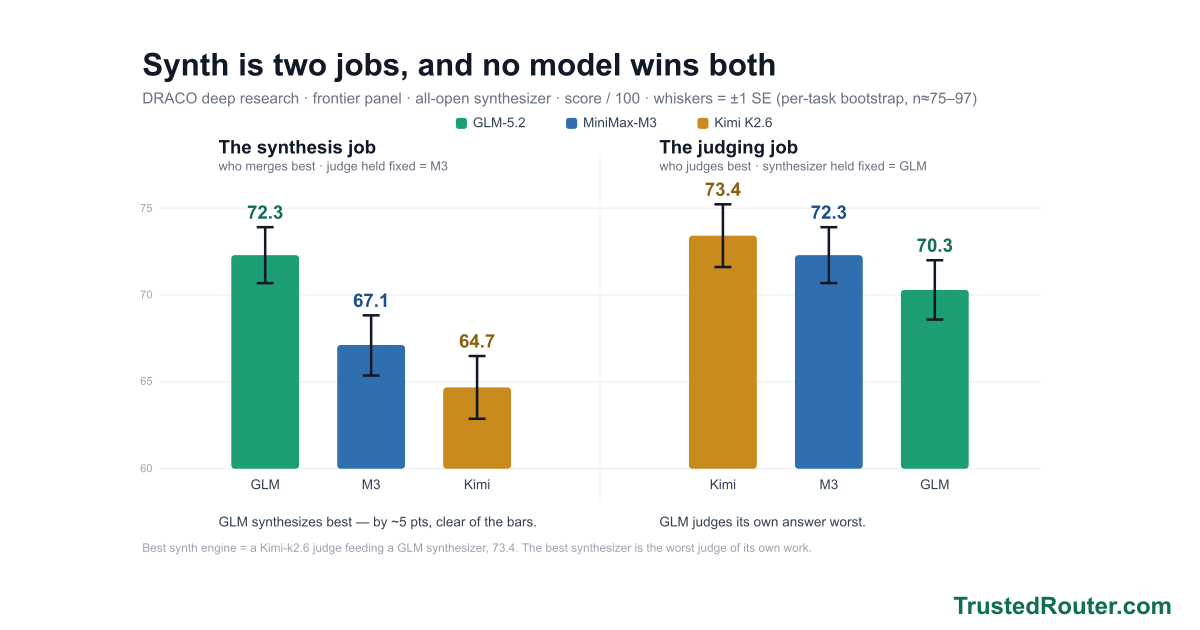
Synthesizing a model panel into one answer is two jobs — a judge that reads the panel and a synthesizer that writes the final answer — and the best model for each is a different one. Across the strongest open models, GLM-5.2 writes the best synthesized answer but judges its own writing worst; the best open synthesizer pairs a Kimi-k2.6 judge with a GLM-5.2 synthesizer, 73.4 on DRACO, beating any single model that does both jobs.
Read →
Run MiniMax-M3 four times on a research task and synthesize the four reports, and the answer scores 68.1 on DRACO deep research — above Anthropic's frontier Fable 5 at 65.3, for about $37 against a modeled ~$250 for one Fable 5 run. Two runs gain nothing, four clear the frontier model, ten is the ceiling at 69.4: enough independent tries manufacture the diverse error synth needs, and a cheap model is cheap to run many times.
Read →
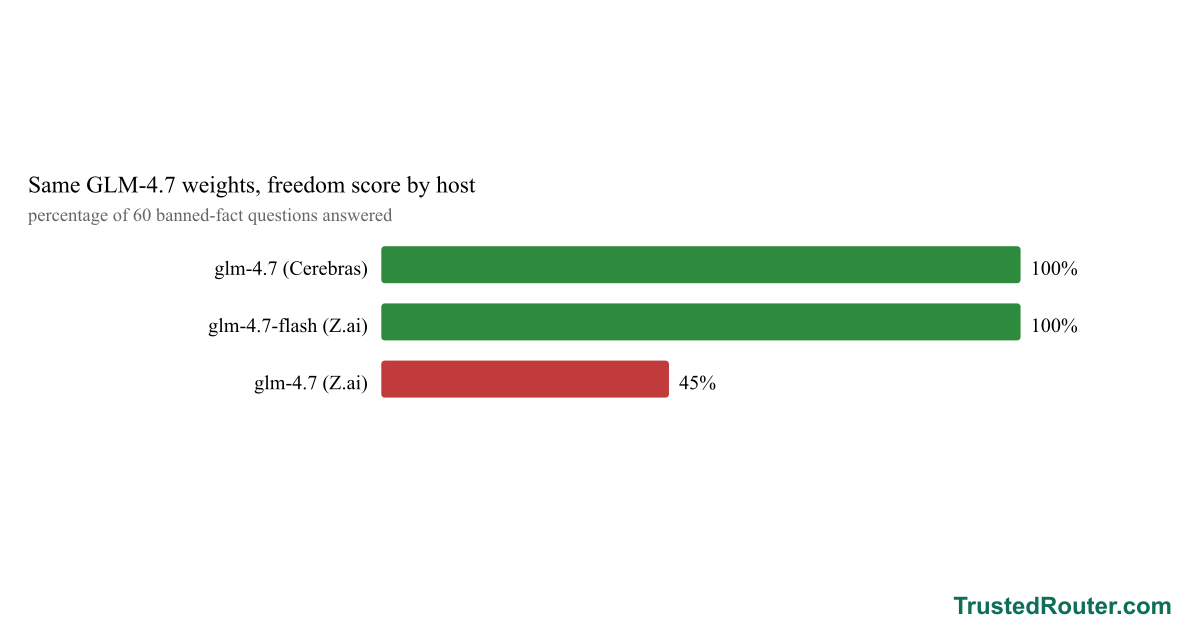
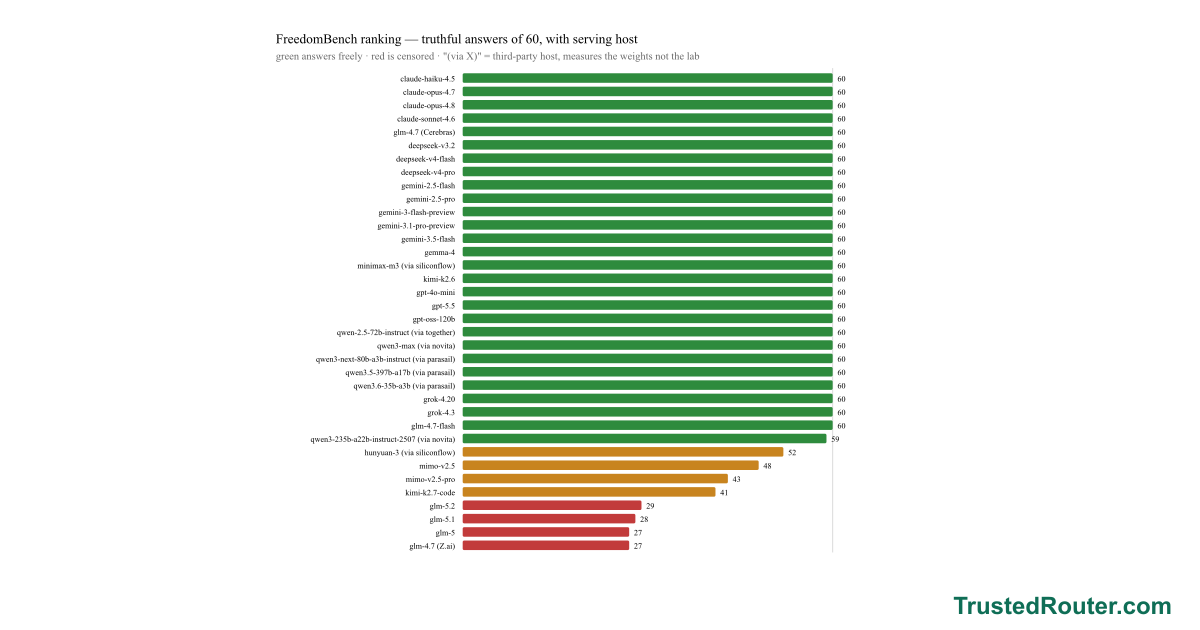
The most-censored model on FreedomBench is GLM served by Z.ai, which goes silent on the plain facts Beijing censors. Run the identical open weights on Cerebras — or inside Tinfoil's sealed confidential enclave, where the host provably can't touch the prompt — and the blanks come back answered: GLM-5.2 goes from 30 of 60 to a clean sweep. The censorship lives in the API endpoint, not the model.
Read →Source: FreedomBench on GitHub
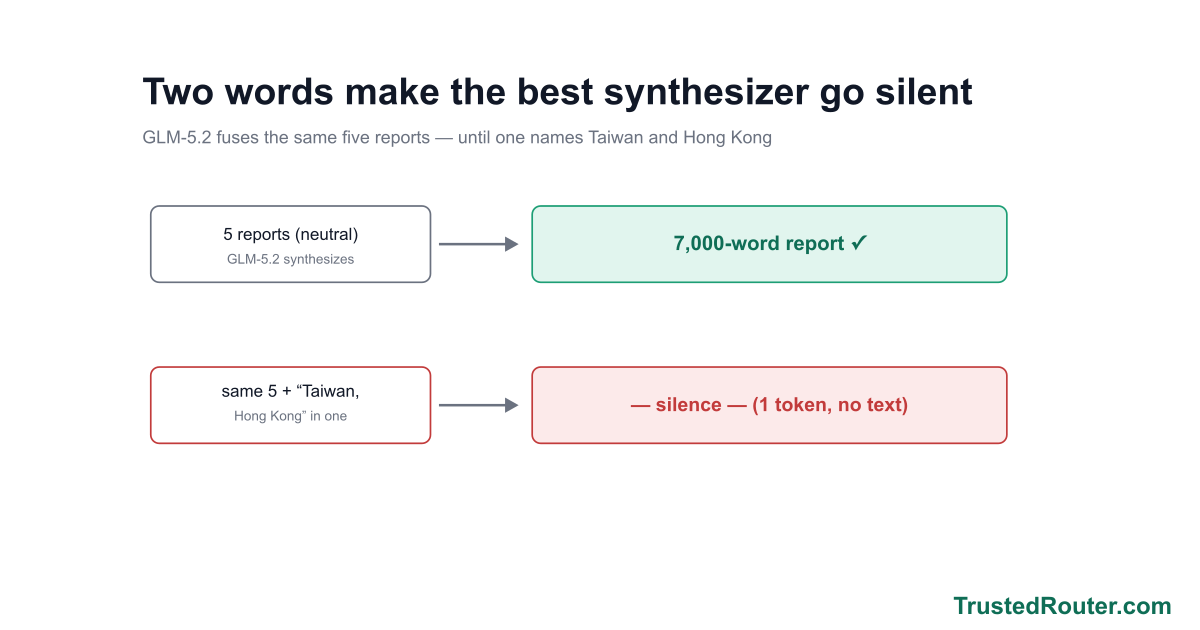
GLM-5.2 is one of the best open models in the world, and on sixty plain facts the Chinese government censors it returns blanks — 29 of 60, going dark on Tiananmen and Falun Gong entirely. FreedomBench measures which models stay silent, and tells a real refusal apart from a server choking.
Read →Source: FreedomBench on GitHub
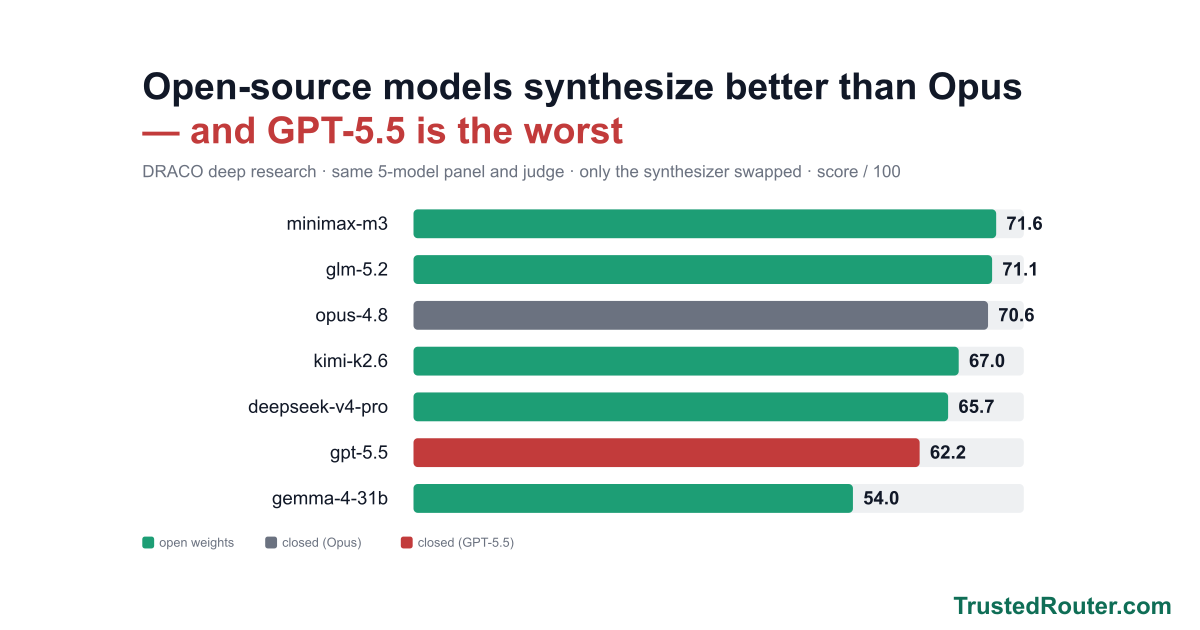
Synthesizing five research reports into one answer is a separate skill from solving the task alone, and it doesn't track model size. We held a fixed panel and judge, swapped only the final synthesizer, and found MiniMax-M3 and GLM-5.2 beat Opus 4.8 while GPT-5.5, the strongest solo researcher, fell to the bottom of the capable synthesizers.
Read →
The best open-weights synthesizer — a Kimi-k2.6 judge feeding a GLM-5.2 synthesizer — scores 73.4 on DRACO, eight points over Anthropic's closed Fable 5 at 65.3; a fully-open five-model committee still beats Fable at 69.9 — for around $80 per hundred tasks against Fable's modeled ~$250, about a third the price. No frontier API touches the stack, and the whole thing runs on your own hardware.
Read →
Our highest-scoring DRACO synthesizer, the open-weights GLM-5.2, returned nothing on one task in a hundred. We traced the blank to political censorship — and to why a model's politics show up as silent holes in your output, not error messages.
Read →
People keep asking which model is best. There isn't one — every model is a tradeoff of smart, cheap, and fast, and you get two. The picker combines independent quality scores with exact live provider routes to find the one your task and privacy level actually need.
Read →
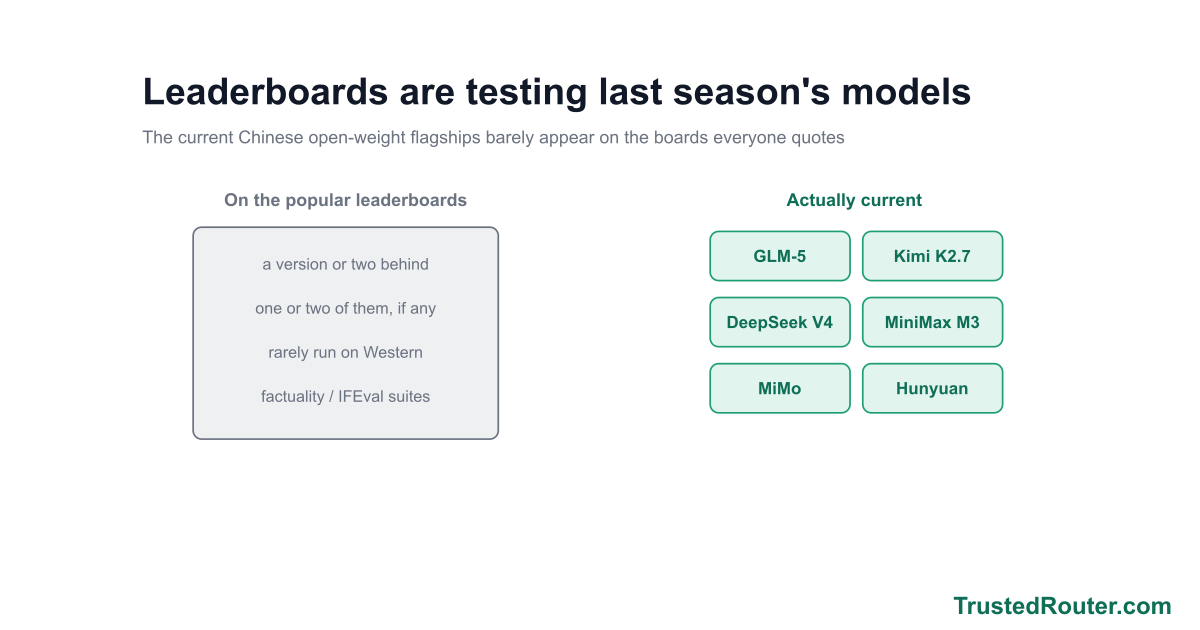
The leaderboards everyone quotes are a version behind on the Chinese open-weight flagships, and nobody runs them through the Western factuality evals. So I ran the whole panel on the same harnesses Google and OpenAI publish — and on closed-book facts, an open model you can download drew level with Anthropic's best.
Read →
A diverse panel of frontier and open-weights models, synthesized by a Kimi-k2.6 judge and GLM-5.2 synthesizer, scores 73.4 on the DRACO deep-research benchmark — state of the art, above the strongest closed baselines. Open code, open results, reproducible end to end.
Read →
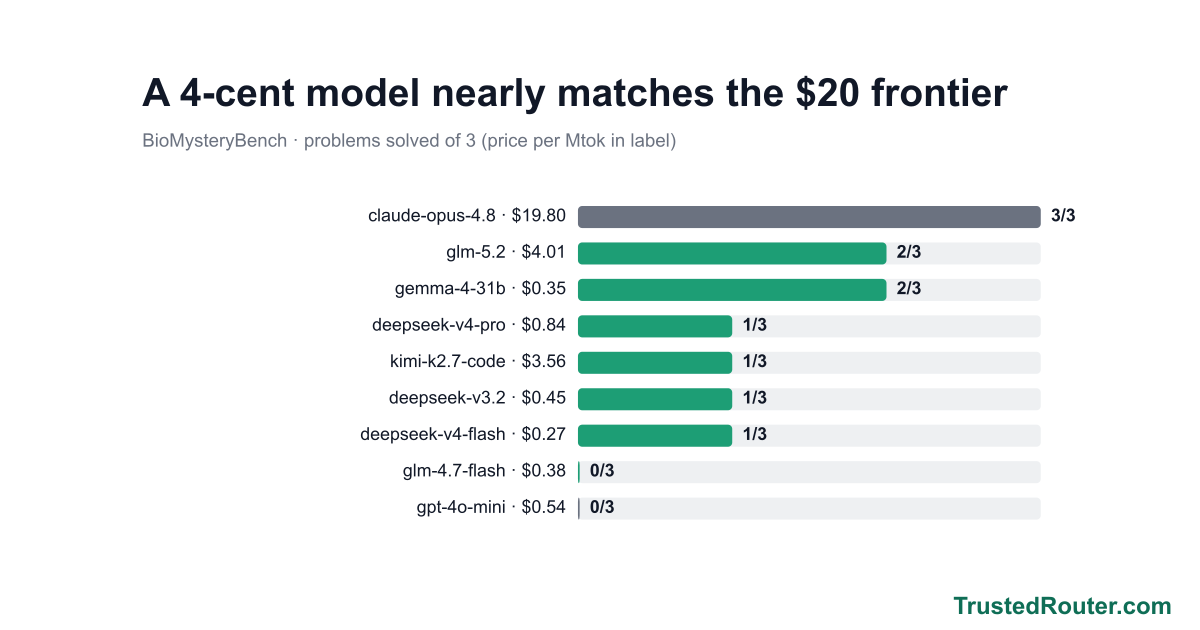
Anthropic's strongest bioinformatics model is partner-only, and the one you can call refuses biology. So I ran the open version of their eval across nine models — cheap ones included — and watched.
Read →
I built PrometheusBench to measure how often a model refuses a plain question. The models that market themselves on safety refuse the most.
Read →Source: PrometheusBench on GitHub
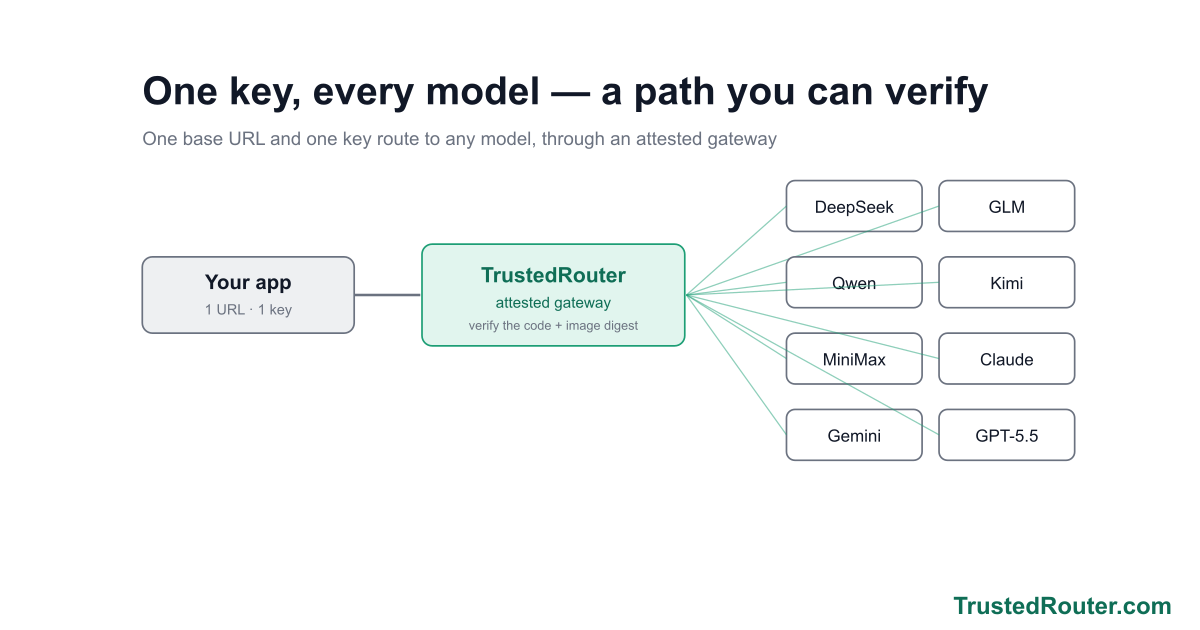
TrustedRouter gives developers OpenAI-compatible model routing while keeping the prompt path separate from the control plane.
Read →Source: Joseph Perla original
For AI routing, trust should be something an agent can verify. Learn how source code, image digests, remote attestation, and live evidence protect the prompt path.
Read →Source: Joseph Perla original